 5b2fe374fc
* storage: add Store::find_all_ec_volumes for split-disk EC lookups

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: add merge_ec_runtimes to resolve a vid's per-disk shard set

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: replace dead slots.get(14) assertion with a width-14 pin

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: build the checksum scrub plan from every per-disk runtime

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: build the local scrub plan from every per-disk runtime

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: prove the local scrub plan reaches every runtime's slots

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: make the scrub plan tests falsifiable

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: report unverifiable protection when the sidecar predates the scrubbed encode

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: commit sidecar provenance with the sidecar it describes

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* volume server: scrub every disk's EC shards for CHECKSUM and LOCAL

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: run the FULL/READS parity check across split-disk shards

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* volume server: report fenced-out runtimes in FULL/READS scrubs

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: tighten verify_ec_shards ordering and missing-shard coverage

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* volume server: visit each EC volume id once in node-wide scrubs

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: cover split-disk scrub aggregation end to end

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* volume server: pin fenced-out disks and sibling-disk shards in EC scrubs

Three scrub behaviors shipped without a test at the RPC seam. Task 8
showed the seam exists, so close them here.

FULL/READS (mode 2|5) now marks a volume broken when the identity fence
excludes a runtime, where it previously reported clean. Pinned against a
control fixture whose two disks AGREE and scrub clean, so the test fails
on the clean->broken transition, not only on the message text. That needs
a structurally valid, tombstone-only .ecx (so the needle walk finds
nothing to complain about) and a seeded shard-location cache (so the
absent master does not short-circuit the scrub with an error of its own).

LOCAL (mode 3) and CHECKSUM (mode 4) now build their plans from every
per-disk runtime. Made observable by moving shard 0 -- the shard the
volume's single needle spans and the one the checksum sidecar is checked
against -- to the SIBLING disk, leaving shard 5 on the disk the singular
find_ec_volume lookup returns. Built from that disk alone, neither scrub
ever looks at shard 0.

The split-disk fixture grows a config struct rather than more positional
arguments; its defaults reproduce the existing layout byte for byte, so
the node-wide dedupe test is unchanged.

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: report fenced-out disks on a malformed sidecar too

`errors.extend(self.skipped)` sat below the whole status match, so only
`(Some(p), On)` ever reached it. The Invalid arm already returns a
non-empty error vector of its own, so the Go-parity contract that
silences the Off arm (`case BitrotOff: return 0, nil, nil`) does not
reach it -- appending the fence lines there costs nothing that contract
protects. A volume with BOTH a malformed sidecar and a disk the identity
fence excluded reported only the sidecar, hiding the unscanned disk
behind an unrelated integrity error.

Off stays byte-identical, and so does the `(None, On)` arm that is
documented as treating a missing payload defensively as protection off.
Off is now the ONLY status that drops the report, and the comment at the
On-path copy says so: that is the one place the parity constraint costs
us coverage.

Also corrects a false claim in the FULL/READS test's doc comment. It
said a fenced-out disk "is a disk this scrub did NOT read", which is true
only of the merge-driven parity half. The per-needle walk still resolves
`store.find_ec_volume` (store_ec.rs:281) and binds
`expected_encode_ts_ns` to that runtime (:311) -- position 0, the
EXCLUDED one on that fixture -- so `read_local_intervals`' generation
filter (:1204) makes it read the excluded disk and treat the anchor's
shards as non-local, the inverse of what `skipped` reports. The fixture's
tombstone-only .ecx walks nothing, so the test cannot tell the two apart;
the comment now says that rather than implying coverage it does not have.

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: take CHECKSUM's bitrot protection from the disk that has the sidecar

`EcChecksumScrubPlan::for_volumes` read `(prot, status)` off the ANCHOR.
The anchor is the first shard-bearing runtime at the maximum `encode_ts_ns`,
chosen with no regard for which disk holds the `.ecsum`.

That sidecar is deliberately NOT mirrored across disks -- `ec_metadata_dirs()`
exists so one authoritative copy stays reachable rather than being duplicated
-- and at mount `EcVolume::new` resolves it via `load_active_bitrot_sidecar(&[])`
with no sibling directories at all; only the `VolumeEcShardsMount` RPC ever
passes `ec_metadata_dirs()`. So after EVERY volume-server restart, the
split-disk runtime that does not physically hold the sidecar mounts
`BitrotStatus::Off`. When the one copy lives on disk 1 and the anchor is disk 0,
`run()` hit `case BitrotOff` and returned `(0, [], [])`: the whole volume
scrubbed clean, silently. That is the steady state for roughly half of all
mirrored split-disk layouts, and it is the exact failure this branch exists to
remove.

Source protection from the first MERGED runtime that has any -- `On` if one
does, else `Invalid`, else the anchor's `Off`. Two facts make that safe, and
both are load-bearing:

  - Every runtime that mounted `On` already passed the `geometry_matches` gate
    in `load_bitrot_for_generation`, so its manifest agrees with the volume's
    layout. A sidecar that contradicted it would have failed the mount.
  - All merged runtimes share the same `encode_ts_ns` by construction of the
    identity fence, so a sidecar from any of them describes the same encode run.

The `unverifiable_sidecar` provenance rule four lines down read
`anchor.bitrot_source_dir`; it now reads the SAME runtime `prot` came from.
Otherwise the two would describe different sidecars and the rule would vouch
for a manifest nobody is scanning against. One consequence worth naming: that
source dir is now non-empty by construction (a runtime with protection found a
file), where the anchor's was often "" and short-circuited the rule -- so on a
fenced volume whose anchor had no sidecar, an unverifiable-protection note now
surfaces where previously nothing was reported at all.

`run()` is untouched, and the `BitrotStatus::Off` arm still returns
`(0, [], [])` exactly, for Go parity with `case BitrotOff: return 0, nil, nil`.
`parity_shards` still comes from the anchor while `prot` may come from a
sibling; the geometry gate above makes them agree, and slot-width agreement is
handled separately.

The test drives mode 4 through the real RPC against a split-disk volume whose
sidecar exists only on dir1, and asserts up front that the anchor mounted `Off`
and the sibling `On` -- otherwise it would prove nothing. Reverting this commit's
one-line source change makes it report `[]` instead of `[0, 5]`.

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: pin the slot width, contain the shard-size fallback, and cover multi-disk FULL

Five findings from the whole-branch review, none of which changes what a
healthy volume reports.

Slot width was undefined and the two consumers disagreed (ec_volume.rs).
`merge_ec_runtimes` sizes `slots` to the WIDEST merged runtime, but the identity
fence keys on `encode_ts_ns` alone and never on geometry -- so two
same-generation runtimes whose `.vif`s disagree do merge. The mode 2|5 arm
truncates to the anchor's `data+parity` and silently drops the surplus slots,
while `EcChecksumScrubPlan::for_volumes` iterated the full width and emitted
"present but missing from sidecar manifest" for exactly those ids. Nothing in
the volume describes them -- the sidecar manifest and the Reed-Solomon matrix
are both the anchor's -- so that message was the width disagreement talking, not
a finding. The `slots` field doc now states the contract (the range is the
anchor's geometry; every consumer truncates to it) and CHECKSUM truncates.

The LOCAL `shard_size` fallback had grown a node-wide blast radius
(ec_volume.rs). `anchor.shard_file_size()` returns the anchor's FIRST held
shard, not a maximum. Before aggregation the plan read only that runtime's own
shards, so a truncated shard was contained to its disk; now that one value sizes
every merged sibling's shards, mis-offsetting `locate_data` and manufacturing
needle corruption across the node. Take the max over the merged slots, which is
how `verify_ec_shards` already answers the same question
(`if size > shard_size { shard_size = size }`). Only on the legacy
`dat_file_size == 0` path.

Multi-disk `all_local` had no end-to-end test (grpc_server.rs). The parity check
is gated on every shard being present, and the one all-local fixture keeps them
in a single directory, so every entry of `dirs` is the same string and a
permutation or off-by-one in the `slots` -> `dirs` mapping is invisible;
`test_verify_ec_shards_reads_shards_from_multiple_dirs` builds its `dirs` by
hand and never goes through `merge_ec_runtimes`. The new fixture is a real 10+4
encode split 0..=6 / 7..=13 across two store locations (the `.dat`/`.idx` stay
outside both, so `prune_incomplete_ec_with_sibling_dat` has nothing to act on),
driven through the real RPC: clean first, then a corrupted PARITY shard on the
SECOND disk -- which only the parity half can see, and only through a correct
mapping. Shifting that mapping by one, or computing `all_local` from the anchor
alone, both make it report `[]` instead of `[13]`.

Deleted `test_ec_volume_enumeration_is_deduped` (store_ec_reconcile.rs). It
built `raw` from `store.locations` and then applied its OWN inline
`filter(|v| seen.insert(*v))`, asserting on that -- a property of
`HashSet::insert`, never reaching the production dedupe. That path is covered by
`test_scrub_ec_volume_node_wide_dedupes_a_split_disk_volume`, which does fail
(2 != 1) when the dedupe is removed.

Corrected `test_verify_ec_shards_treats_a_none_dir_as_missing`'s docstring
(ec_encoder.rs). It claimed the unmounted shard "must not drag the shards that
ARE mounted down with it", but `dirs[5] = None` puts shard 5 in `broken_shards`
before the block loop, so every iteration takes the `read_failed` arm and the
parity comparison never runs: corrupting a mounted shard in that fixture changes
nothing about the result. The assertions are unchanged; the docstring now states
what they actually establish.

Also refreshed two comments that cited `shard_file_size() - 1` as the reason
`merge_ec_runtimes` prefers a shard-bearing anchor -- true before this commit,
stale after it.

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: correct the Fix 1 rationale and truncate the shard-size scan

The safety argument attached to `EcChecksumScrubPlan::for_volumes`'s protection
selection was false as written, and it is the argument a reviewer reads first.
`geometry_matches` compares a sidecar against the MOUNTING runtime's own
data/parity/block size, not the anchor's, and returns true vacuously when
`ec_shard_config` is `None` -- so it establishes agreement only when all merged
runtimes share one geometry, which an `encode_ts_ns`-only fence does not
guarantee and which `test_checksum_scrub_truncates_slots_to_the_anchors_geometry`
constructs a counterexample to. The second clause was weaker than stated too: a
`.ecsum` records no encode identity at all, so merged runtimes agreeing on
`encode_ts_ns` does not transfer to the sidecar.

Replace it with the property that is true, checkable from the selection itself,
and stronger for what actually matters. `anchor` is an element of `merged`, so
the `.unwrap_or(anchor)` fallback is reached only when no merged runtime is `On`
and none is `Invalid` -- in which case the anchor is necessarily `Off`. The
status can therefore only move `Off -> On`, `Off -> Invalid` or
`Invalid -> On`; never `On -> Off`, never `Invalid -> Off`. This selection
cannot stop a volume that was being scanned from being scanned, and cannot turn
a reported integrity error into silence: every change it makes is toward more
verification. The comment now also states what it does NOT establish -- geometry
agreement is not guaranteed -- and names geometry fencing as the follow-up that
would close it.

Second, `EcLocalScrubPlan::for_volumes`'s `shard_size` max scanned the FULL slot
width, violating the `slots` contract documented in the same commit that
introduced the max: the volume's shard-id range is the anchor's geometry and
every consumer must truncate to it. Pre-fix that input could not exist, because
`anchor.shard_file_size()` read only the anchor's own anchor-sized vector -- so
the max opened a new, narrow path to the same node-wide mis-sizing it exists to
close (same-generation runtimes with disagreeing `.vif`s, the wider one holding
an out-of-geometry shard larger than the in-geometry ones, `dat_file_size == 0`).
`.take(anchor.data_shards + anchor.parity_shards)` mirrors the truncation
already applied to the CHECKSUM shard scan.

The sibling `shards:` vector is left untruncated on purpose: every access in
`EcLocalScrubPlan::run` is `shards.get(sid)` with `sid < data_shards`, so the
surplus entries are inert.

No behavior change for any healthy volume, and no test added -- the suite is
unchanged at 575 passing, 0 failing, 0 warnings.

Co-Authored-By: Claude Opus 5 (1M context) <noreply@anthropic.com>
Claude-Session: https://claude.ai/code/session_01VUf2cmVKHNhAZPTNv39rDE

* ec: aggregate split-disk runtimes in Go scrubs, mirroring Rust

Go volume scrubs previously used FindEcVolume (first runtime only), so a
volume whose EC shards are split across multiple disks was scrubbed against
just one disk's shards and the others were silently skipped. Node-wide
ScrubEcVolume also appended each disk's EcVolumeIds without deduplication,
scrubbing a split-disk volume once per disk.

Add MergedEcRuntimes/MergeEcRuntimes (Go counterpart to Rust's
merge_ec_runtimes): select the maximum EncodeTsNs as the anchor generation,
fence out runtimes whose encode generation or geometry (DataShards,
ParityShards, BlockSize) disagrees with the anchor, merge shard handles by
shard ID, and report excluded runtimes rather than dropping them. Wire it
into every scrub mode:

- INDEX: scrub the anchor's index, report skipped runtimes.
- LOCAL: aggregate local shards across all merged runtimes via a synthetic
  EcVolume built from the merged shard slots.
- FULL/READS: resolve the runtime matching the anchor's encode generation
  (not the first match) so the needle walk and parity phase inspect one
  encode run; report skipped runtimes.
- CHECKSUM: take bitrot protection from the first merged runtime that has a
  valid sidecar (On, else Invalid, else anchor's Off), preserve invalid
  sidecar errors from every other merged runtime, and report skipped
  runtimes.

Deduplicate EC volume IDs in node-wide ScrubEcVolume so each volume is
scrubbed exactly once.

Refactor ScrubEcVolume to share the per-needle walk via scrubEcVolumeWalk,
called by both the legacy first-runtime path and the new merged path.

Add Go regression tests covering split-disk deduplication, encode-generation
fencing, geometry fencing, sibling-disk LOCAL reach, and merge anchor
selection.

Rust: keep the previously-landed merge/fence/checksum changes intact; revert
incidental cargo-fmt drift from unrelated files so the diff stays focused.

* ec: fence merged CHECKSUM on sidecar encode generation and fix legacy shard size

Address two review findings on the Go merged-runtime scrub:

1. Sidecar provenance: a merged runtime can load a bitrot sidecar from a
   sibling metadata directory (ReloadBitrotSidecar), and the merge fence may
   then exclude the runtime owning that directory. Generation-0 sidecars do
   not identify the encode run, so geometry validation alone cannot prove the
   borrowed manifest describes the anchor shards. If the sidecar records a
   non-zero EncodeTsNs that disagrees with the anchor, refuse the scan
   instead of applying stale checksums to current shards and reporting false
   corruption.

2. Legacy shard size: for volumes without datFileSize in .vif,
   LocateEcShardNeedleInterval derives the shard size from Shards[0].ecdFileSize.
   The merged shard set is compacted in shard-ID order, so a truncated
   lowest-ID shard would shrink every interval and misread intact sibling
   shards. Synthesize a datFileSize from the maximum mounted shard size when
   the anchor lacks one, so the datFileSize>0 path uses the largest shard
   size across all merged runtimes.

* ec: fix copylocks, legacy shard boundary, and encode-aware Rust lookups

Address review findings from CodeRabbit and Devin:

Go (ec_volume_merge.go):
- Remove bitrotLock copy from the synthetic EcVolume: copying a sync.RWMutex
  is a go vet copylocks error. The synthetic volume uses its own zero-value
  mutex; bitrot/bitrotStatus are set directly before ChecksumScrub reads them
  via BitrotProtection(), so no concurrent access occurs.
- Fix legacy shard-size boundary: synthesize datFileSize from
  (maxShardSize - 1) * DataShards, not maxShardSize * DataShards, to match
  the legacy fallback in LocateEcShardNeedleInterval (ecdFileSize - 1). An
  exact large-block boundary is ambiguous; the unadjusted size would select
  an extra large row and misread intact sibling shards.

Rust (store_ec.rs):
- Add find_ec_volume_for_scrub helper that resolves by encode generation
  (not first-match find_ec_volume) and use it in scrub_snapshot_under_lock,
  write_back_shard_locations, and the post-refresh shard-location read.
  Previously the encode-aware lookup was only used for the initial runtime
  selection; the cache write-back and per-needle snapshot still used
  first-match, so a split-disk volume whose first runtime was from an older
  encode run would write to and read from the wrong runtime's shard-location
  cache and falsely abort with 'remounted as a different encode run'.

---------

Co-authored-by: Claude Opus 5 (1M context) <noreply@anthropic.com>
Co-authored-by: Chris Lu <chris.lu@gmail.com>
SeaweedFS


SeaweedFS is a simple and highly scalable distributed file system. There are two objectives:
- to store billions of files!
- to serve the files fast!
One weed binary serves an S3 object store, a POSIX file system, and a lakehouse with S3 Tables, all over the same data. Each blob is one disk read away, capacity grows by starting another volume server, and cloud storage can be cached or tiered transparently.
- Download Binaries for different platforms
- Wiki Documentation
- Community: Slack, Twitter, Telegram, Reddit, Mailing List
- SeaweedFS White Paper and introduction slides: 2025.5, 2021.5, 2019.3
Table of Contents
- Quick Start
- Why SeaweedFS
- Architecture
- Compared to Other Systems
- Benchmark
- Enterprise
- License
- Sponsors
Quick Start
One command
Download the latest binary from the releases page and unzip the single weed (or weed.exe) file, or let the install script put it in /usr/local/bin:
curl -fsSL https://raw.githubusercontent.com/seaweedfs/seaweedfs/master/install.sh | bash
Then start a ready-to-use S3 object store:
AWS_ACCESS_KEY_ID=admin \
AWS_SECRET_ACCESS_KEY=secret \
S3_BUCKET=my-bucket \
./weed mini -dir=./data
That's it. The S3 endpoint is at http://localhost:8333, my-bucket exists, and admin/secret are valid credentials:
AWS_ACCESS_KEY_ID=admin AWS_SECRET_ACCESS_KEY=secret \
  aws --endpoint-url http://localhost:8333 s3 cp README.md s3://my-bucket/
The same process also runs the master, a volume server, the filer, WebDAV, the Iceberg REST catalog, and the Admin UI. Add S3_TABLE_BUCKET=warehouse to also create an Iceberg table bucket, or warehouse:LANCE for a Lance one. Drop the AWS keys to run without authentication for development.
macOS: if the binary is quarantined, run
xattr -d com.apple.quarantine ./weedfirst.
weed mini is auto-tuned for one node and is fine for single-node production, such as an S3 gateway that issues presigned URLs. See Quick Start with weed mini.
Docker
docker run -p 8333:8333 -v weed-data:/data \
  -e AWS_ACCESS_KEY_ID=admin \
  -e AWS_SECRET_ACCESS_KEY=secret \
  -e S3_BUCKET=my-bucket \
  chrislusf/seaweedfs
Same behavior as the weed mini command above.
Docker Compose
To run master, volume server, filer, S3, and WebDAV as separate services:
wget https://raw.githubusercontent.com/seaweedfs/seaweedfs/master/docker/seaweedfs-compose.yml
wget -P prometheus https://raw.githubusercontent.com/seaweedfs/seaweedfs/master/docker/prometheus/prometheus.yml
docker compose -f seaweedfs-compose.yml -p seaweedfs up
Docker Compose for S3 adds credentials, and the docker/compose folder has variants for replication, mounts, message queues, and more.
Kubernetes with Helm
helm repo add seaweedfs https://seaweedfs.github.io/seaweedfs/helm
helm install seaweedfs seaweedfs/seaweedfs -n seaweedfs --create-namespace -f values.yaml
A production-shaped values.yaml for a three-node cluster: two copies of every write, three masters, and an S3 endpoint with credentials and a bucket.
global:
  seaweedfs:
    enableReplication: true
    replicationPlacement: "001"   # one extra copy on another server; "002" for two

master:
  replicas: 3
  data:
    type: persistentVolumeClaim   # the cluster's default storage class; add storageClass to pick one
    size: 1Gi

volume:
  replicas: 3                     # at least 1 + the sum of the replication digits
  dataDirs:
    - name: data
      type: persistentVolumeClaim
      size: 500Gi
      maxVolumes: 0               # size the volume count from the disk

filer:
  replicas: 2
  data:
    type: persistentVolumeClaim
    size: 20Gi

s3:
  enabled: true
  replicas: 2
  enableAuth: true
  credentials:
    admin:
      accessKey: admin
      secretKey: change-me
  createBuckets:
    - name: app-storage
The S3 endpoint is the seaweedfs-s3 service on port 8333. Helm Chart Recipes has values for a development cluster, a lakehouse with the Iceberg catalog exposed, filer metadata on PostgreSQL, and node-local disks. The SeaweedFS Operator and the CSI driver are the other Kubernetes paths.
Build from source
git clone https://github.com/seaweedfs/seaweedfs.git
cd seaweedfs/weed && make install
weed lands in $GOPATH/bin. Getting Started covers running master, volume, filer, and S3 as separate processes.
Scale out
Capacity is a volume server. Start one on any machine with disk and point it at the master:
weed volume -dir=/data -master=<master_host>:9333
Nothing rebalances until you ask it to. Throughput is a filer or S3 gateway; they are stateless, so run as many as you need behind a load balancer. Production Setup walks through a multi-node cluster.
Why SeaweedFS
Fast
- One disk read per blob. A small file is one blob; a large file is split into chunks of a few MB, each its own blob. A volume server keeps a 16-byte index entry per blob in memory and reads it in a single seek, also for erasure-coded data.
- The master is not in the read path. Clients cache the volume-to-server mapping and talk to volume servers directly.
- 40 bytes of metadata per file on disk. Small files are packed into append-only volume files, so there is no per-file inode, no per-file metadata file, no fragmentation, and writes are SSD friendly.
- Hot data is replicated; erasure coding is applied to warm data in the background, so writes never pay the encoding cost.
- The Rust volume server is a drop-in for higher throughput and lower tail latency on the same on-disk format.
On one laptop, weed benchmark writes 1KB files at 15,700 per second and reads them back at 47,000 per second, and a mixed S3 warp run totals 3.2 GiB/s. Numbers are in the Benchmark section; throughput grows with volume servers and gateways.
Scalable
- The master tracks volumes, not files. A cluster with billions of files has a few thousand volumes, so the master stays small. One master is enough for most clusters; run three for Raft failover.
- Adding a server adds capacity with no data reshuffle. Balancing, vacuum, erasure coding, and repair run on demand from
weed shellor the maintenance worker. - Filer and S3 gateways are stateless and scale linearly. Directory metadata lives in a store you already run: LevelDB, RocksDB, SQLite, MySQL, PostgreSQL, Cassandra, HBase, MongoDB, Redis, Elasticsearch, etcd, TiKV, FoundationDB, YDB, ArangoDB, Tarantool, and MySQL or PostgreSQL compatible databases such as TiDB, CockroachDB, and MemSQL.
- Rack and data center aware replication, tiered storage across disk types, and transparent cloud tiering for unlimited capacity.
- Files from a byte to tens of TB. Volumes up to 8TB with the large-disk build.
The most complete S3 API
The S3 gateway implements the object, bucket, S3 Tables, IAM, and STS APIs on one endpoint, so the AWS SDKs and CLI, rclone, restic, Spark, and Trino work unchanged.
| API | Operations |
|---|---|
| S3 bucket and object | 73 |
| S3 Tables | 36 |
| IAM | 39 |
| STS | 5 |
- Versioning, Object Lock with retention and legal hold, lifecycle rules, tagging, CORS, conditional reads and writes, checksums, presigned URLs, browser POST uploads, multipart uploads, and an atomic RenameObject.
- Bucket policies with conditions and variables; IAM users, groups, and policies; STS with OIDC, LDAP, and Kubernetes service accounts.
- SSE-S3, SSE-KMS, and SSE-C server-side encryption, with OpenBao and Vault, AWS KMS, Azure Key Vault, and GCP KMS as key providers.
- Audit log, bucket quota, and rate limiting.
- Each bucket is its own collection, so deleting a bucket is instant.
The full operation list is in Amazon S3 API, and Supported APIs vs MinIO compares. The S3 compatibility suite and the SDK, IAM, SSE, policy, and Spark integration tests run in CI on every change.
A data warehouse with S3 Tables
SeaweedFS is a lakehouse in one system. S3 Table Buckets hold Apache Iceberg tables by default, or Lance tables for vectors and multimodal data, and the built-in Iceberg REST Catalog and Lance namespace serve them directly. There is no Hive Metastore, Glue, or separate catalog service to deploy, secure, and back up.
- Query engines operate on the same tables at the same time: Spark, Trino, Dremio, DuckDB, Apache Doris, RisingWave, ClickHouse, and LanceDB. Catalog commits are atomic compare-and-swap, so concurrent writers are safe. Lakekeeper can front the same storage with STS-vended credentials.
- Automated table maintenance: compaction, snapshot expiration, orphan file removal, and manifest rewriting, configured per bucket or table through the S3 Tables maintenance APIs, and the same for Lance.
- IAM at the bucket, namespace, and table level with standard bucket policies, see S3 Tables Security.
- A Hadoop compatible file system for Spark, Flink, and HBase.
S3_TABLE_BUCKET=warehouse ./weed mini -dir=./data brings the whole stack up on a laptop.
A fast cache for cloud storage
Cloud Drive mounts a bucket from S3, Google Cloud Storage, Azure, Backblaze B2, Wasabi, Storj, or any S3-compatible store into SeaweedFS and serves it at local speed:
- Metadata is pulled once, so listing, stat, and directory walks cost no cloud API calls.
- File content is downloaded once, on first read or warmed by folder, name pattern, size, or age, and cached with the capacity of the whole cluster: cache everything, no churn.
- Local writes complete at local latency and are written back to the cloud asynchronously in the cloud's native layout, so other tools keep reading the bucket directly.
- Uncache by the same rules to free local disk while keeping the metadata.
Cloud Tier goes the other direction, moving whole warm volumes to cloud storage while keeping one-read access, and the Gateway to Remote Object Storage mirrors every bucket to a remote store. Faster and cheaper than reading the cloud directly.
Active-active replication and more
- Active-active or active-passive replication between clusters, continuous and resumable, for the whole tree or chosen folders, across data centers.
- Filer store replication for metadata HA, async backup to cloud storage, metadata backup, and change data capture with webhooks on every metadata event.
- The same data as a FUSE mount on Linux, macOS, and Windows, over WebDAV, SFTP, HDFS, HTTP, and TUS resumable uploads; on Kubernetes through the CSI driver and Operator.
- AES256-GCM encryption at rest, TLS and mTLS between components, JWT-signed volume access, and FIPS builds.
- Admin UI, Prometheus metrics, TTL per file or volume, automatic compression and compaction, and seaweed-up for bare-metal clusters.
Architecture
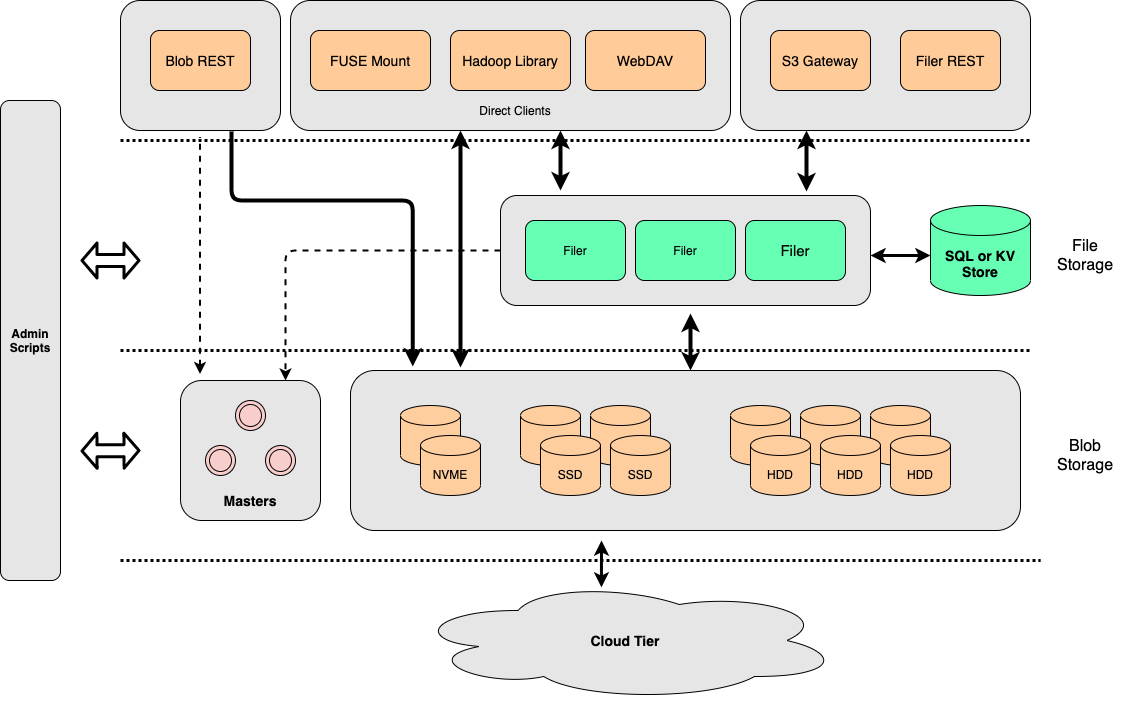
- Master servers, one or a Raft group of three, track which volume lives on which volume server and hand out file ids. They are not in the read path.
- Volume servers store blobs in append-only volume files, keep a 16-byte in-memory index per blob, and replicate or erasure-code at the volume level.
- Filer servers add directories and files on top, with metadata in a store of your choice, and expose HTTP, S3, WebDAV, SFTP, FUSE, and the table catalogs.
The blob store started from Facebook's Haystack, erasure coding takes ideas from f4, and the whole has a lot in common with Tectonic and Colossus. How file ids are assigned, written, and looked up, and why a master that tracks volumes scales, is in Blob Store Architecture; the services are in Components and the white paper.
Compared to Other Systems
Most other distributed file systems seem more complicated than necessary.
SeaweedFS is meant to be fast and simple, in both setup and operation. If you do not understand how it works when you reach here, we've failed! Please raise an issue with any questions or update this file with clarifications.
SeaweedFS is constantly moving forward. Same with other systems. These comparisons can be outdated quickly. Please help to keep them updated.
Compared to HDFS
HDFS uses the chunk approach for each file, and is ideal for storing large files.
SeaweedFS is ideal for serving relatively smaller files quickly and concurrently.
SeaweedFS can also store extra large files by splitting them into manageable data chunks, and store the file ids of the data chunks into a meta chunk. This is managed by "weed upload/download" tool, and the weed master or volume servers are agnostic about it.
Compared to GlusterFS, Ceph
The architectures are mostly the same. SeaweedFS aims to store and read files fast, with a simple and flat architecture. The main differences are
- SeaweedFS optimizes for small files, ensuring O(1) disk seek operation, and can also handle large files.
- SeaweedFS statically assigns a volume id for a file. Locating file content becomes just a lookup of the volume id, which can be easily cached.
- SeaweedFS Filer metadata store can be any well-known and proven data store, e.g., Redis, Cassandra, HBase, Mongodb, Elastic Search, MySql, Postgres, Sqlite, MemSql, TiDB, CockroachDB, Etcd, YDB etc, and is easy to customize.
- SeaweedFS Volume server also communicates directly with clients via HTTP, supporting range queries, direct uploads, etc.
| System | File Metadata | File Content Read | POSIX | REST API | Optimized for large number of small files |
|---|---|---|---|---|---|
| SeaweedFS | lookup volume id, cacheable | O(1) disk seek | Yes | Yes | |
| SeaweedFS Filer | Linearly Scalable, Customizable | O(1) disk seek | FUSE | Yes | Yes |
| GlusterFS | hashing | FUSE, NFS | |||
| Ceph | hashing + rules | FUSE | Yes | ||
| MooseFS | in memory | FUSE | No | ||
| MinIO | separate meta file per drive for each file | Yes | No | ||
| RustFS | separate meta file per drive for each file | Yes | No |
GlusterFS stores files, both directories and content, in configurable volumes called "bricks". It hashes the path and filename into ids, and assigned to virtual volumes, and then mapped to "bricks".
Compared to MooseFS
MooseFS chooses to neglect small file issue. From moosefs 3.0 manual, "even a small file will occupy 64KiB plus additionally 4KiB of checksums and 1KiB for the header", because it "was initially designed for keeping large amounts (like several thousands) of very big files"
MooseFS Master Server keeps all meta data in memory. Same issue as HDFS namenode.
Compared to Ceph
Ceph can be setup similar to SeaweedFS as a key->blob store. It is much more complicated, with the need to support layers on top of it. Here is a more detailed comparison
SeaweedFS has a centralized master group to look up free volumes, while Ceph uses hashing and metadata servers to locate its objects. Having a centralized master makes it easy to code and manage.
Ceph, like SeaweedFS, is based on the object store RADOS. Ceph is rather complicated with mixed reviews.
Ceph uses CRUSH hashing to automatically manage data placement, which is efficient to locate the data. But the data has to be placed according to the CRUSH algorithm. Any wrong configuration would cause data loss. Topology changes, such as adding new servers to increase capacity, will cause data migration with high IO cost to fit the CRUSH algorithm. SeaweedFS places data by assigning them to any writable volumes. If writes to one volume failed, just pick another volume to write. Adding more volumes is also as simple as it can be.
SeaweedFS is optimized for small files. Small files are stored as one continuous block of content, with at most 8 unused bytes between files. Small file access is O(1) disk read.
SeaweedFS Filer uses off-the-shelf stores, such as MySql, Postgres, Sqlite, Mongodb, Redis, Elastic Search, Cassandra, HBase, MemSql, TiDB, CockroachCB, Etcd, YDB, to manage file directories. These stores are proven, scalable, and easier to manage.
| SeaweedFS | comparable to Ceph | advantage |
|---|---|---|
| Master | MDS | simpler |
| Volume | OSD | optimized for small files |
| Filer | Ceph FS | linearly scalable, Customizable, O(1) or O(logN) |
Compared to MinIO, RustFS
Please note, as Apr 25, 2026 MinIO ceased development. It's strongly discouraged to use that unmaintained software with multiple security bugs. RustFS is a MinIO reimplementation in Rust, Apache 2.0 licensed and still developed, keeping MinIO's storage model down to a byte-compatible on-disk format. So the points below apply to both.
MinIO followed AWS S3 closely and was ideal for testing for S3 API. It had good UI, policies, versionings, etc. SeaweedFS is trying to catch up here.
The metadata are in simple files. Each file write incurs extra writes to the corresponding meta file, on every drive of the erasure set. Changing only tags or retention rewrites that meta file on all of them, so the write amplification does not shrink with object size.
There is no optimization for lots of small files. The files are simply stored as is to local disks. Plus the extra meta file and shards for erasure coding, it only amplifies the LOSF problem.
Multiple disk IO are needed to read one file. SeaweedFS has O(1) disk reads, even for erasure coded files.
Erasure coding is full-time. SeaweedFS uses replication on hot data for faster speed and optionally applies erasure coding on warm data.
No POSIX-like API support.
There are specific requirements on storage layout, which makes it hard to scale out and to maintain. An erasure set must be 2 to 16 drives and must divide the drive list symmetrically, and capacity grows or shrinks a whole pool at a time. In SeaweedFS, just start one volume server pointing to the master. That's all.
Benchmark
Unscientific single-machine numbers from a MacBook with an SSD. weed benchmark, 1 million 1KB files, concurrency 16:
| Requests per second | p50 | p99 | |
|---|---|---|---|
| Write | 15,708 | 0.8 ms | 2.6 ms |
| Random read | 47,019 | 0.3 ms | 0.7 ms |
make benchmark runs warp mixed S3 traffic against a local weed server:
Mixed operations.
Operation: DELETE, 10%, Concurrency: 20, Ran 42s.
 * Throughput: 55.13 obj/s

Operation: GET, 45%, Concurrency: 20, Ran 42s.
 * Throughput: 2477.45 MiB/s, 247.75 obj/s

Operation: PUT, 15%, Concurrency: 20, Ran 42s.
 * Throughput: 825.85 MiB/s, 82.59 obj/s

Operation: STAT, 30%, Concurrency: 20, Ran 42s.
 * Throughput: 165.27 obj/s

Cluster Total: 3302.88 MiB/s, 550.51 obj/s over 43s.
Read throughput is bounded by the random read speed of the disks, and grows with every volume server added. More numbers, including multi-node, FUSE, and Hadoop, are in Benchmarks, S3 API Benchmark, FIO benchmark, and Independent Benchmarks.
Enterprise
For enterprise users, please visit seaweedfs.com for the SeaweedFS Enterprise Edition, which has advanced features, including data recovery, self-healing storage, customizable erasure coding, EC vacuum and repair, etc.
License
Licensed under the Apache License, Version 2.0 (the "License"); you may not use this file except in compliance with the License. You may obtain a copy of the License at
http://www.apache.org/licenses/LICENSE-2.0
Unless required by applicable law or agreed to in writing, software distributed under the License is distributed on an "AS IS" BASIS, WITHOUT WARRANTIES OR CONDITIONS OF ANY KIND, either express or implied. See the License for the specific language governing permissions and limitations under the License.
The text of this page is available for modification and reuse under the terms of the Creative Commons Attribution-Sharealike 3.0 Unported License and the GNU Free Documentation License (unversioned, with no invariant sections, front-cover texts, or back-cover texts).
Sponsors
Sponsor SeaweedFS via Patreon
SeaweedFS is an independent Apache-licensed open source project with its ongoing development made possible entirely thanks to the support of these awesome backers. If you'd like to grow SeaweedFS even stronger, please consider joining our sponsors on Patreon.
Your support will be really appreciated by me and other supporters!
Gold Sponsors


Star History
